Generative AI Video Models: How to Choose the Right One
 RoboNeo TeamSeptember 22, 2026
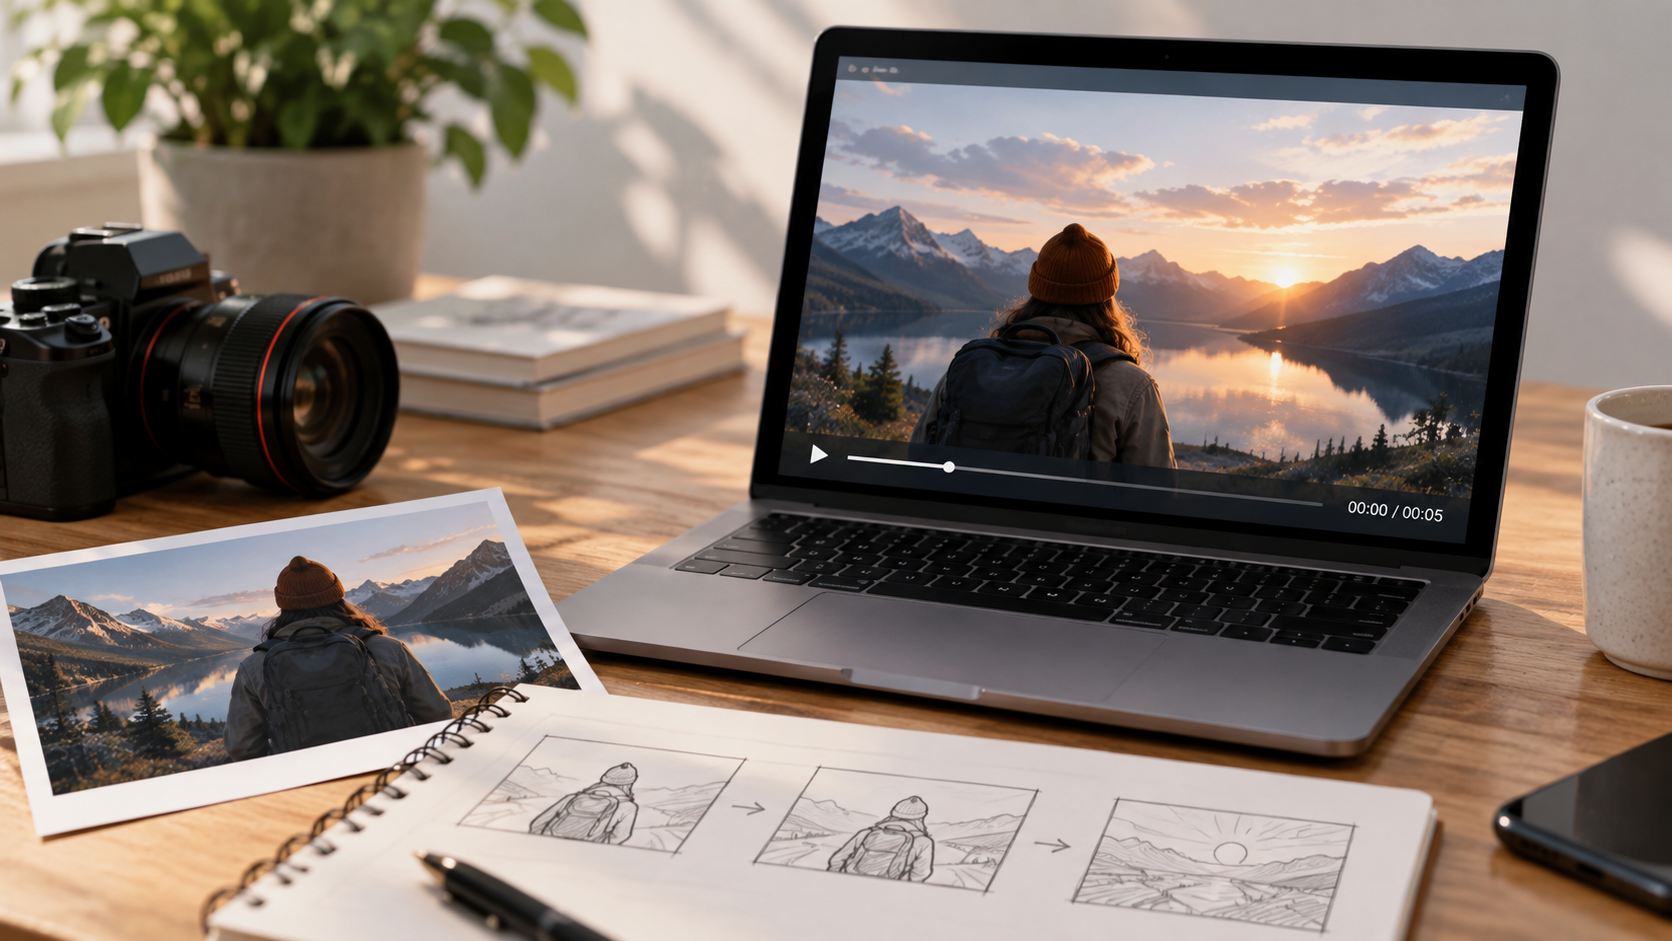
The right AI video generation model depends on what you want to create and what material you already have. Text-to-video works when you are starting with an idea, image-to-video gives you more control over a person or product, video-to-video builds on existing motion, and multimodal models combine several types of reference material. This guide explains the main types of generative AI video models, compares popular options by use case, and covers the practical factors to check before choosing one.
What AI Video Generation Models Do
AI video generation models create moving footage from prompts or reference material. Unlike image models, they must keep a scene coherent across many frames while handling appearance, motion, camera direction, lighting, and background changes.
Inputs can include text, images, video, audio, or a combination of them. The output is usually a short clip rather than a finished video, so captions, music, branding, or editing may still be needed.
Some newer video generation AI models can also create dialogue, ambient sound, or effects. The model provides the core generation capability, while the AI video maker or platform determines which version, inputs, controls, and export options users can access.
Main Types of AI Video Generation Models
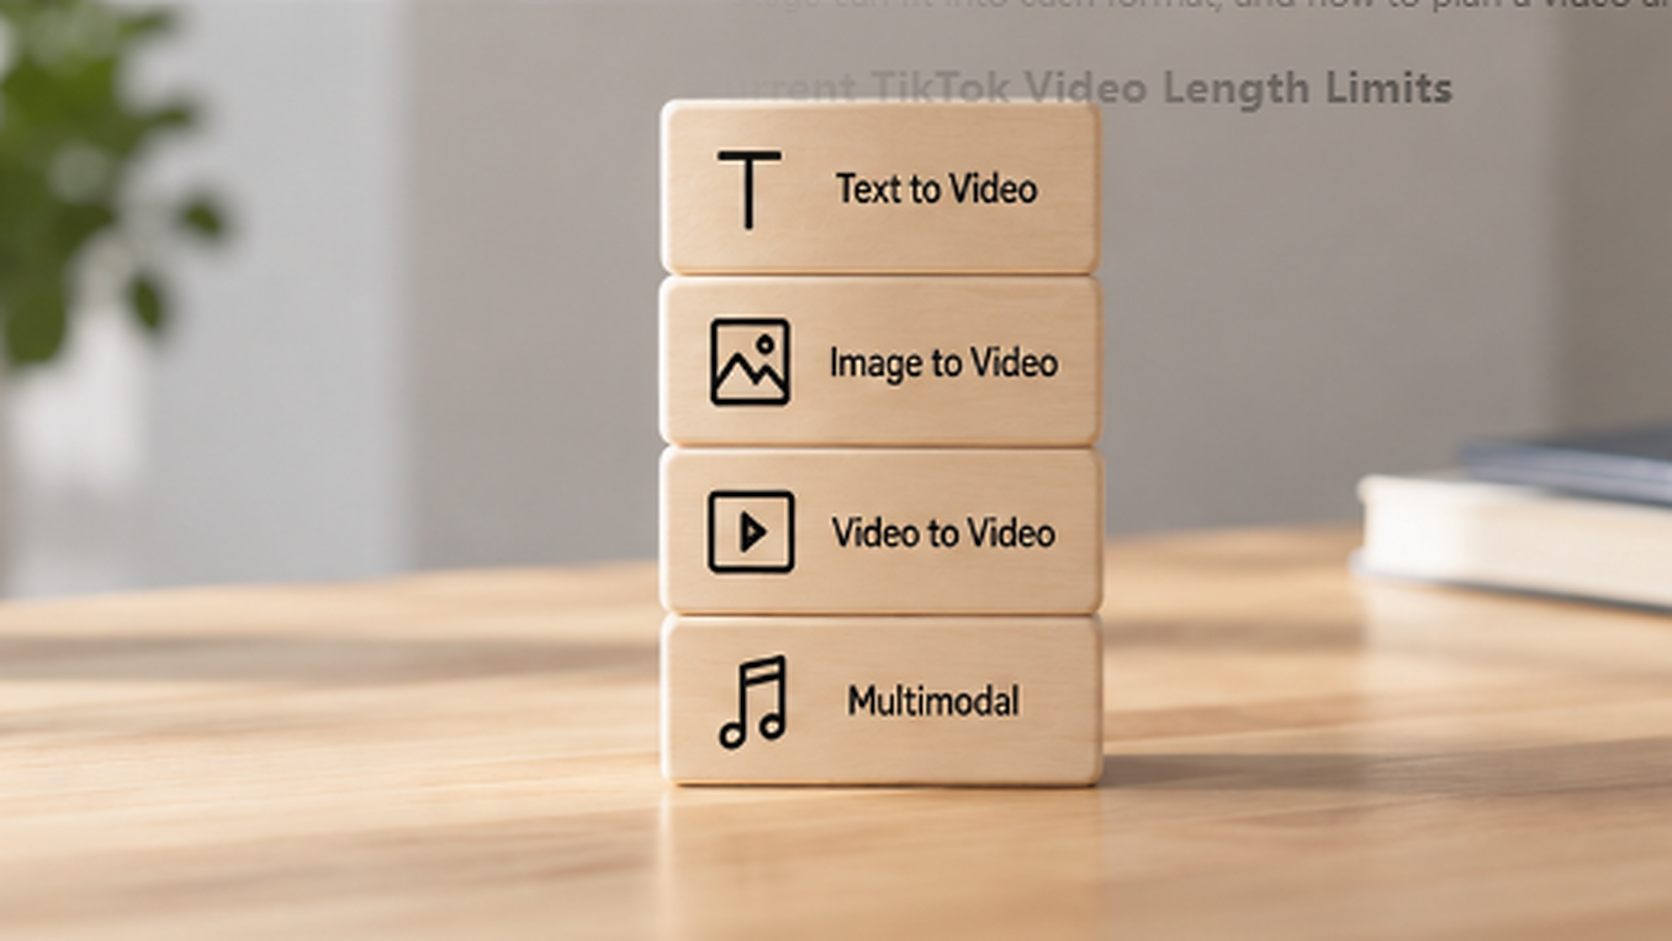
The easiest way to compare AI models for video generation is by the material they use as a starting point.
Text-to-Video Models
Text-to-video models create a scene from a written prompt. Users can describe the subject, setting, action, lighting, style, and camera movement.
A creator planning a sci-fi short could ask for a motorcycle moving through a rainy city while the camera tracks beside it. The model must invent the rider, street, lighting, motion, and composition.
This approach works well for concept footage, imaginary environments, and projects without existing visual assets, making it a common starting point for creators learning how to make AI videos.
Its main weakness is consistency. Since the model must invent most visual details, repeated generations may change faces, clothing, objects, or framing. When a product or character needs to maintain a precise appearance, text alone may not provide enough control.
Image-to-Video Models
Image-to-video models start with an existing still image and add motion, camera movement, or environmental changes.
The image already defines the subject, colors, composition, and style. A fashion brand could animate a campaign image with a slow camera push and subtle fabric movement. A product team could turn a clean render into a short showcase without asking the model to recreate the object from text.
This gives the model a clearer visual target, although large movements can still change faces, hands, packaging, or backgrounds.
Video-to-Video Models
Video-to-video models use an existing clip as the motion foundation. The source footage already contains timing, body movement, subject position, and camera direction, while the model changes the visual treatment.
A performer filmed in a plain studio could be placed in a stylized fantasy environment without recreating the choreography. This works well for visual effects, style changes, background redesign, and performance-based content.
Motion blur, blocked subjects, fast gestures, or objects leaving the frame can reduce stability.
Multimodal Video Models
Multimodal models can combine text, images, video, or audio in one workflow.
A product campaign might use a product image for appearance, a reference clip for camera movement, and text for the setting. Audio can also guide dialogue or timing when supported.
This is useful when several parts of a shot need control at once. Platform support still varies, so check the exact model version, accepted file types, reference limits, and available controls before production.
AI Video Models Compared by Their Best Use
Different models suit different production goals. The useful question is not which model is best overall, but which one fits the shot you need.
| Model | Best Use | Input Options | Standout Strength | Audio | Main Limitation |
| Seedance | Fast-paced short videos | Varies by version | Dynamic motion | Version-dependent | Complex interactions need testing |
| Veo | Cinematic scenes | Text and visual references | Cinematic visuals and sound | Supported in some versions | Access varies |
| Kling | Character and product animation | Text and images | Image-led animation | Version-dependent | Large movements may reduce consistency |
| Runway | Controlled shots and editing | Text, images, video | Generation plus editing tools | Workflow-dependent | More control adds complexity |
| Sora | Story-driven concepts | Text and supported visual inputs | Narrative scene creation | Product-dependent | Multi-shot continuity needs review |
Seedance for Fast-Paced Short Videos
Seedance fits short clips with strong motion, changing camera angles, and quick pacing. Social posts, ad concepts, character action, product atmosphere shots, and short narrative scenes are common use cases.
Creators using Seedance in RoboNeo can check the exact model version and supported reference inputs before generating.
A sportswear clip may need a person turning quickly while the camera follows, while a product teaser may rely on a fast orbit around one object. Complex hand interaction, multiple people, and precise product structures still need testing.
Veo for Cinematic Video With Sound
Veo is a strong candidate when cinematic visuals and sound both matter.
Narrative scenes, commercial concepts, environmental shots, and dialogue-driven clips can benefit from native audio. A cafe scene could combine camera movement, room ambience, kitchen noise, and speech in one generation.
Native audio can reduce editing work, but lip sync, dialogue accuracy, and speaker matching still need review. Reference support and other controls may also differ by version or access point.
Kling for Character and Product Animation
Kling is useful when a project starts with a clear character image, product photo, or fixed composition.
A cosmetics brand could animate an existing bottle shot instead of asking the model to recreate the packaging from text. Character performances and image-based social content can use the same approach.
Clear source images usually improve stability. Strong gestures, hand interaction, multiple people, and large perspective changes can still alter the subject.
Runway for Controlled Shots and Video Editing
Runway suits creators who want generation and editing in the same broader workflow.
Advertising, visual effects, concept footage, and video transformation can benefit from reference images, keyframes, and editing tools. That extra control can help with multi-shot production, while a simple five-second social clip may not need it.
Sora for Story-Driven Video Concepts
Sora works well for turning scene descriptions and story ideas into visual clips.
It can help with narrative concepts, imagined environments, and early-stage visual development. A filmmaker could visualize a character entering a crowded station before planning the final shoot.
Longer stories are better divided into separate shots. Common AI video generation limitations become more noticeable when one generation has to handle several locations, actions, and character interactions.
Choosing a Model for Your Video Project
The final deliverable often matters more than a long feature list.
Social Media Shorts
Short-form content benefits from fast generation, clear movement, vertical-friendly output, and manageable cost per usable clip.
A single subject performing one clear action usually works better than several events packed into a few seconds. Seedance, Kling, and other models focused on short-form motion are practical candidates, especially when generation speed matters more than advanced controls.
Product and Brand Videos
Product videos place more pressure on visual accuracy. Reference-image support, stable geometry, correct colors, packaging, and logo placement can matter more than dramatic camera movement.
AI works well for lifestyle footage and atmospheric product shots. A sneaker can appear in a stylized city environment, while a close-up showing the exact sole design may still be better captured with real footage.
Commercial work should also account for export resolution, watermarks, privacy policies, and usage rights.
Character-Based Stories
Character-driven projects need consistent references across multiple shots.
It is usually easier to establish the character design first and generate scenes separately. Different viewpoints may also require additional reference images because one front-facing portrait does not fully define side or full-body views.
If dialogue is important, audio generation and lip synchronization also become part of the model comparison.
Cinematic and Commercial Shots
Cinematic work puts more emphasis on camera control, composition, lighting, output quality, and movement stability.
Veo, Runway, Sora, and other models with cinematic or camera-focused features can all be tested against the actual shot requirements. Provider showcases are not enough on their own; test the actor movement, product structure, or camera path your project actually needs.
Cost and Limitations to Check Before You Commit
A model name does not tell you the full project cost. Retries, failed generations, extensions, and export settings can add up quickly.
Before choosing a platform or model, check:
The exact model version and supported inputs
Generation length, resolution, aspect ratio, and watermark rules
Costs for retries, extensions, and high-resolution exports
Access to audio, reference video, frames-to-video workflows, and other advanced controls
Privacy policies for customer footage, brand assets, and unreleased products
Commercial-use terms under the current plan
Free credits may cover basic testing but not a multi-shot project. Ten usable clips can require far more than ten generations once retries are included. Model updates can also change output, pricing, and available controls.
FAQ
Which AI video generation model is best?
There is no single best model for every project. The right choice depends on your source material, subject, motion, audio needs, budget, and output requirements. Test candidates with the type of shot you actually plan to create instead of relying only on showcase videos.
Is image-to-video better than text-to-video?
They serve different purposes. Text-to-video is useful when creating a scene from scratch, while image-to-video gives the model a defined subject and composition. If keeping a character or product recognizable matters most, image-to-video is often the better option to test first.
Can AI video models generate audio?
Some models can generate dialogue, ambient sound, and effects, while others produce silent footage. Audio support may vary by model version or platform. Even with native sound, dialogue accuracy, lip sync, and overall audio quality still need review.
Can one model create an entire video?
A simple single-shot clip may only need one model. Longer videos often combine character scenes, establishing shots, product close-ups, and different motion styles. Using different models for different shots and combining them in an editor can be more practical.
Why does the same model cost more on some platforms?
Platforms use different credit systems, subscriptions, and feature packages. Resolution, processing speed, storage, editing tools, and export options can all affect the price. The same model family may also be offered in different versions, so compare the actual cost of producing one usable clip rather than credit numbers alone.
You May Be Interested
What Are Foundation Models in Generative AI? Types, Uses & Examples
What AI Model Writes Stories Best? 7 Tools Compared
What Is An AI Model? A Guide to Types, Examples, and Uses
How to Repair Video Blocking Artifacts: Causes and Fixes
How to Create Animated Videos: 5 AI Methods to Final Video