What Are Foundation Models in Generative AI: A Quick Guide
 RoboNeo TeamSeptember 19, 2026
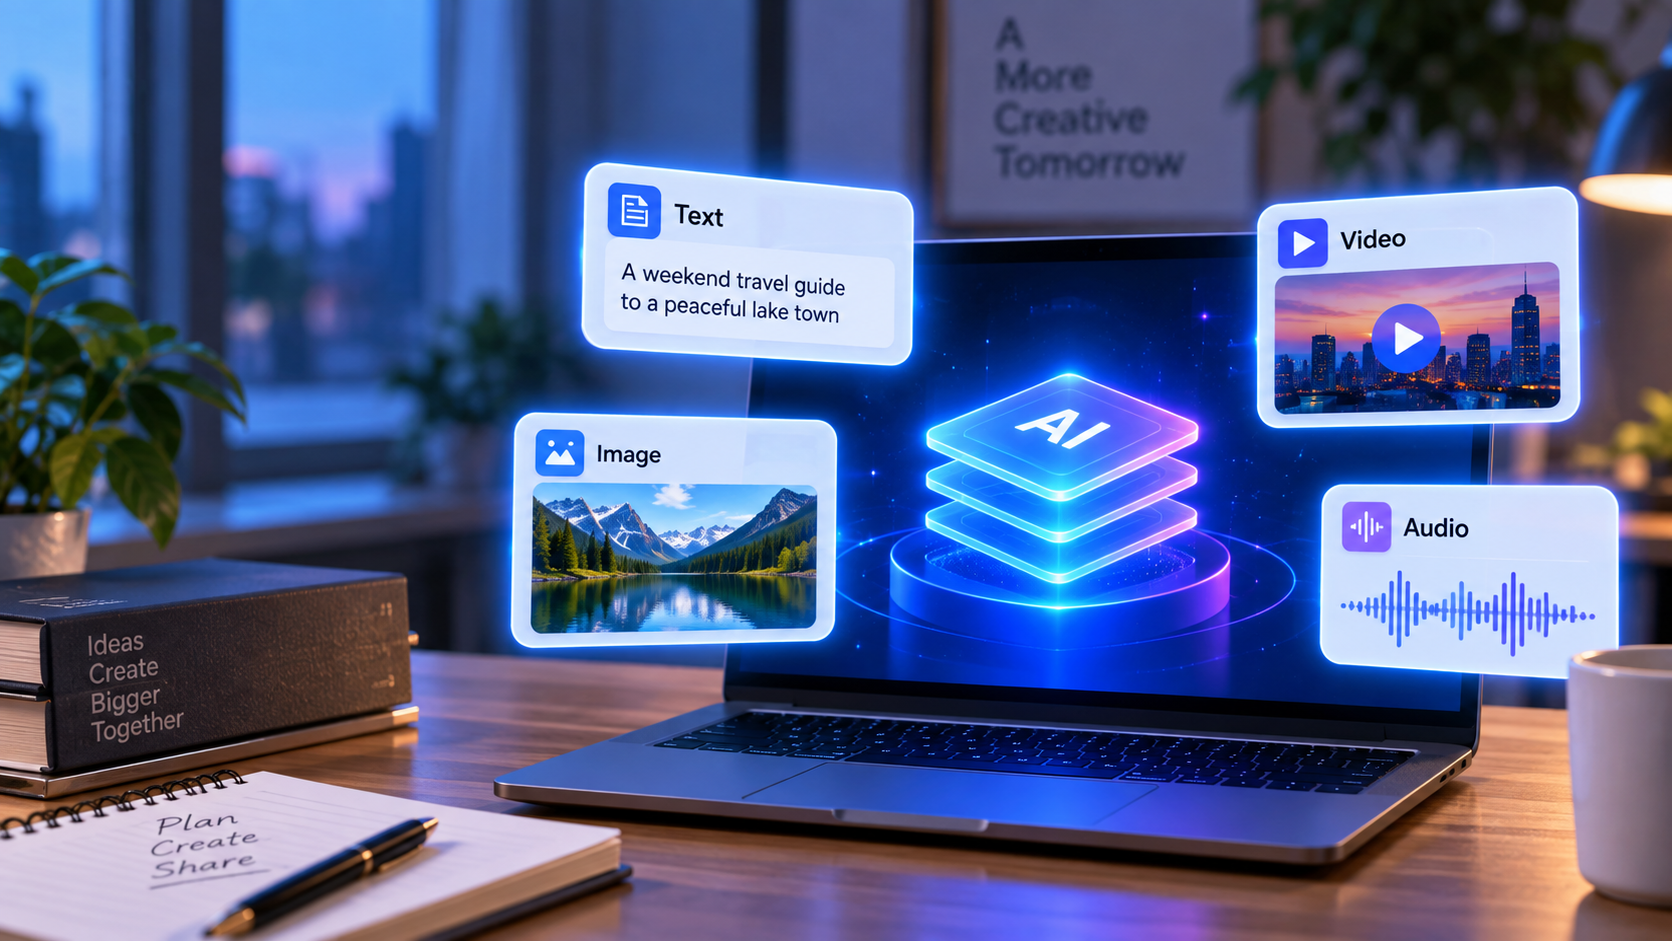
Foundation models are AI models pretrained on large, diverse datasets so they can develop broad capabilities across language, images, audio, video, and other data. Unlike systems built for one narrow task, they can be adapted for many uses, from writing and coding to image and video generation.
This guide explains what foundation models are, how they work, their main types and uses, and the limitations to consider before relying on their output.
What Are Foundation Models?
Foundation models are large AI models trained on broad datasets rather than for one narrowly defined task. Their general capabilities can later be adapted for writing, question answering, coding, analysis, image creation, video generation, and other uses.
This helps explain what are the foundation models in generative AI designed to be: reusable model bases that can support different applications instead of being rebuilt for every task. GPT, Claude, Gemini, Llama, and Stable Diffusion are model families associated with this approach.
The model is also different from the product built around it. ChatGPT, for instance, is a product that uses underlying models and adds a chat interface, file handling, tools, and other features around them. The word "foundation" describes the model's reusable role, not a guarantee that every output will be accurate.
How Foundation Models Work
A foundation model begins with broad pretraining and becomes useful for a specific task through prompts, context, or further customization.
Pretraining on Broad Data
Training starts with large collections of text, code, images, audio, video, or other data. The model learns recurring patterns and relationships.
A language model develops relationships between words, concepts, and context. An image model learns how written descriptions connect with visual elements such as objects, color, composition, and lighting. Internal parameters are adjusted repeatedly as the system reduces prediction errors.
Data quality, coverage, training methods, and model design all affect what the finished model can do well.
Prompts and Context Define the Task
A pretrained model may have broad capabilities, but it still needs direction for the current request. Prompts can specify the goal, audience, tone, constraints, and desired format.
A project manager might upload meeting notes and ask for a short summary with action items. A creator preparing a video could define the topic, runtime, viewer, and tone before asking for a script. The same applies when building a best prompt for YouTube script: clearer context gives the model less room to guess.
Ordinary prompting guides the current task without directly retraining the underlying model.
Customization for Specific Needs
Fine-tuning can reinforce a particular format, tone, or task pattern over time. Retrieval-augmented generation, or RAG, works differently by retrieving relevant information and supplies it as context.
A company assistant could pull from current HR documents before answering an employee's benefits question. Both approaches can make a general model more useful for specialized work, but results still need testing.
Producing the Final Output
The final result depends on the model, prompt, reference material, and tools around it. Outputs may include text, code, images, audio, or video.
An AI product can also add search, formatting, editing controls, or safety checks. Creative outputs may vary even with similar prompts, so important results still need review.
Main Types and Examples of Foundation Models
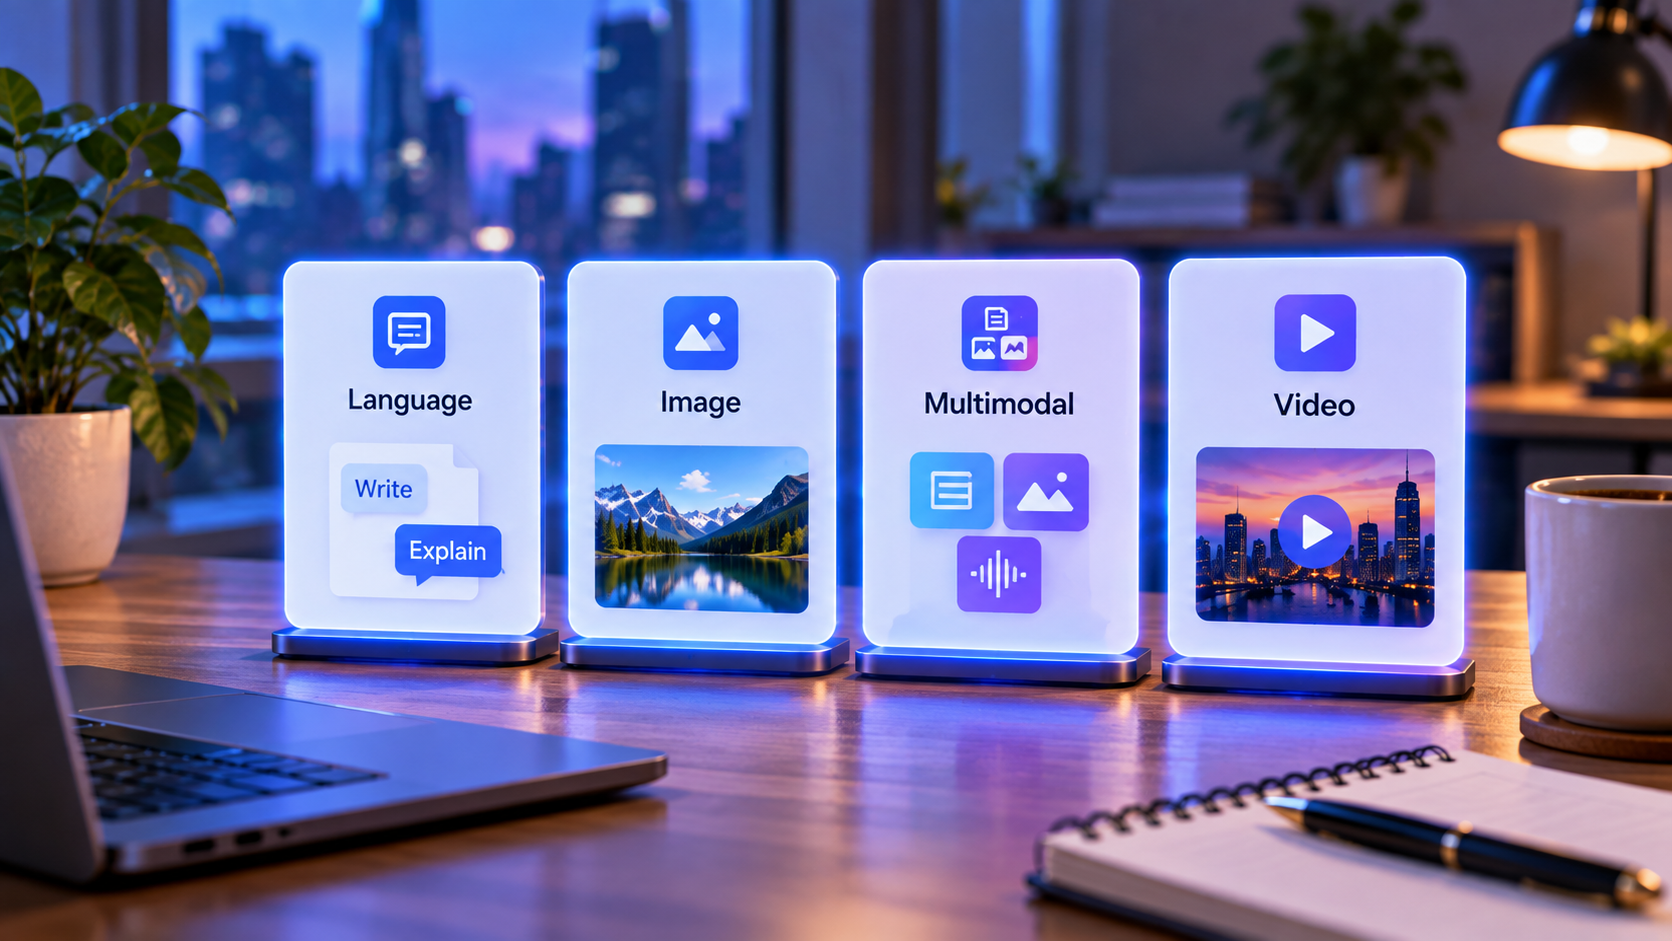
The phrase what are foundational models in generative AI covers several model categories. The main difference is often the type of information a model is designed to understand or generate.
| Model Type | Common Examples | Best For | Main Limitation |
| Language | GPT, Claude, Llama | Writing, coding, summarization, analysis | Can produce incorrect information |
| Image | Stable Diffusion | Illustration, concepts, image generation and editing | Fine details may be inconsistent |
| Multimodal | Gemini, multimodal GPT models | Mixed text, image, file, and media tasks | Capabilities vary by version |
| Video | Seedance, Veo, Kling | Ads, product scenes, stories, social video | Motion and continuity can be difficult |
Language Foundation Models
Language models are trained mainly on large amounts of text and code. They can answer questions, summarize documents, translate content, draft copy, and assist with programming.
A marketing team might turn a product brief into landing-page copy, while a developer asks the same model family to explain unfamiliar code. Fluent language is not proof of factual accuracy, so important claims and technical details still need verification.
Image Foundation Models
Image models learn relationships between language and visual characteristics such as objects, composition, color, and style. They can create images from text and, depending on the system, edit existing images.
Stable Diffusion is a familiar example, while systems such as GPT Image 2 focus on image generation and editing with detailed instructions. These models can support concept art, advertising drafts, and product visualization.
Text, exact product geometry, hands, or complex poses may still require several attempts or manual correction.
Multimodal Foundation Models
Multimodal models work with more than one type of information together. A user could upload a chart and a report, then ask the model to explain how the numbers relate to the written findings.
Gemini and some GPT models support combinations of text, images, audio, files, and other inputs. Capabilities still vary by version, so a system that can analyze an image does not automatically support video generation or every other media type.
Video Foundation Models
Video models must account for appearance and changes over time. They learn patterns involving movement, object interaction, camera motion, and the relationship between consecutive frames.
Seedance 2.0, Veo, and Kling are video-generation model families used for creative production. A small brand could turn a product image and short description into a social media clip without a full physical shoot.
Model version, supported inputs, clip length, credit use, and export conditions can affect which model fits a project. Complex scenes with several people or detailed physical actions can still create continuity problems.
Common Uses of Foundation Models
Foundation models can support work ranging from communication to media production and research.
Writing and Communication
Language models can draft emails, reports, scripts, product descriptions, and social posts. They can also summarize documents, adjust tone, translate content, or turn meeting notes into action items.
For video-focused work, an AI script generator can apply language-model capabilities to scenes, dialogue, and structured scripts. Anything sent to customers or published publicly should still be checked for facts, outdated details, and brand consistency.
Coding and Data Work
Foundation models can explain unfamiliar code, draft functions, suggest fixes for common errors, and turn plain-language instructions into technical steps.
They can also help create database queries or extract information from spreadsheets and documents. Generated code still needs review and testing because security issues or logic errors may not be obvious at first glance.
Marketing and Media
Generative models can support several stages of creative production, including copy, visual concepts, scripts, voice content, and video.
A product launch might begin with campaign ideas, move into visual mockups, and then produce short social clips for testing. The RoboNeo can bring different video models into one creative environment so creators can choose an option that fits the project.
Publication still requires checks for product accuracy, logos, permissions, recognizable people, and copyright concerns.
Explore AI Models with RoboNeo
Business and Research
Businesses use foundation models to organize documents, support customer service, search internal information, and analyze large amounts of material. Research teams may use them to review papers, examine code, interpret images, or organize experimental notes.
Medical, legal, and financial work requires stronger safeguards because a model can assist with information processing without replacing qualified professional judgment.
Limits and Risks of Foundation Models
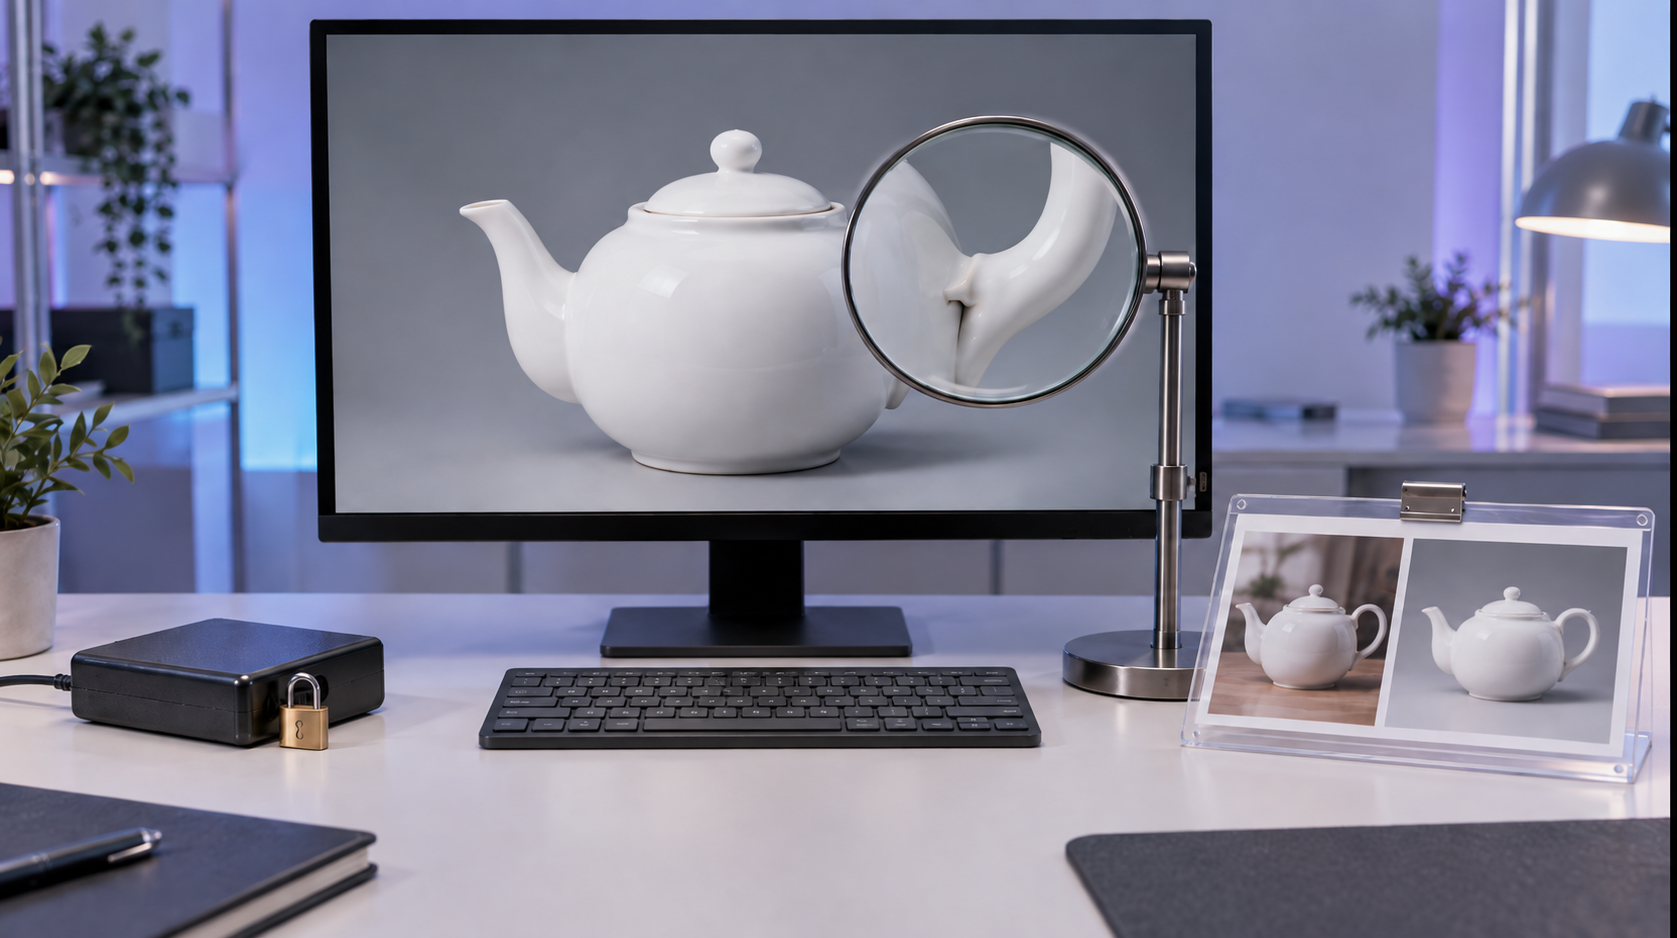
Foundation models are flexible, but accuracy, privacy, intellectual property, cost, and operational control still matter in regular use.
Incorrect or Unreliable Results
A model can produce a confident answer that is partly or completely wrong. Missing context, ambiguous instructions, or outdated material can increase this risk.
Different model types also fail in different ways:
Language models may invent facts or sources.
Image models can distort text, hands, or object details.
Video models may lose consistency in motion, subjects, or objects across frames.
Important outputs should be checked against reliable information, human review, or practical testing.
Bias, Privacy, and Copyright
Bias in training data can affect how a model represents people, topics, or situations. Privacy becomes another concern when users upload customer information, internal documents, or personal data.
Generated media may also involve copyright, trademarks, likeness rights, or other permissions. Commercial-use terms do not automatically guarantee that every output is free from third-party rights issues.
Cost and Control
Training a large foundation model from scratch requires substantial data, computing resources, and technical expertise. Most businesses and individuals instead use existing models through AI products or APIs.
Usage costs can vary with text length, generation volume, image resolution, video duration, output quality, and model choice. When comparing the best AI video generators, model access, supported inputs, output quality, and usage limits can affect the practical cost of a project.
External providers may also change prices, versions, or access rules, so teams that depend on AI should test updates and keep alternative options available.
FAQ
Are foundation models the same as generative AI?
No. A foundation model is a broadly pretrained model that can be adapted to different tasks. Generative AI refers to systems that create new content such as text, images, audio, or video. Many generative AI tools use foundation models, but foundation models can also support non-generative tasks.
What is an example of a foundation model?
GPT is a well-known language foundation model family used for writing, question answering, summarization, and coding. Stable Diffusion is associated with image generation, Gemini includes multimodal models, and Seedance and Veo are used for video generation.
Is ChatGPT a foundation model?
ChatGPT is more accurately described as an AI product built around underlying models. GPT models provide core language and multimodal capabilities, while ChatGPT adds the interface, file support, tools, safety systems, and other product features.
What is the difference between a foundation model and an LLM?
An LLM focuses mainly on understanding and generating language. A foundation model is a broader category that can include language, image, audio, video, and other models. Many LLMs are foundation models, but not every foundation model is an LLM.
Can a foundation model be customized?
Yes. Prompts can guide individual tasks, retrieval systems can provide specialized information, and fine-tuning can reinforce recurring formats or task patterns. Any customized system still needs testing for accuracy, safety, and consistency.
You May Be Interested
What Is An AI Model? A Guide to Types, Examples, and Uses
What Is AI Video: How It Works and How to Get Started
Best Free AI Text to Video Generators 2026: 7 Tools
Best Setup for AI Video Generation: Benefits, Setup & Tips
Best Image to Video AI: 7 Generators Compared for 2026